

Science
Synthetic Users: Merging Qualitative and Quantitative Research, in seconds.
At Synthetic Users we are blurring the lines between qualitative and quantitative research. Here's how we are going about it now: one calibrated population, from 20 interviews to 200,000 respondents, scored in public.
When we first wrote this post, the claim was simple.
With Synthetic Users, 10 interviews and 5,000 surveys take the same effort.
That's still true.
But effort was never the interesting part.
The interesting part is whether the number at the end means anything.
This is how we got there, and how we check.
The equivalence of effort: Qualitative vs. Quantitative
Qualitative research, with its interviews, focus groups and case studies, has always been slow.
Quantitative research, with its surveys and questionnaires, scales but goes shallow.
Creswell set out the split in "Research Design: Qualitative, Quantitative, and Mixed Methods Approaches."
Qual probes behaviour, emotion and motivation.
Quant generalises through statistics.
With Synthetic Users, the line goes faint.
The same calibrated population answers both.
Twenty in-depth interviews in the morning.
Two hundred thousand respondents in the afternoon.
Same people, same cost of asking.
What a synthetic number actually is
Here's the part most synthetic research skips.
A survey of 1,000 organic people is a sample.
A survey of 1,000 synthetic users is a model's estimate.
Treating the second like the first is how teams fool themselves.
So we hold quant to a stricter test than qual.
A synthetic population earns credit only on instruments it never saw.
It gets scored against that instrument within its own sampling noise.
The honest bar is never zero. We publish how we score it.
The engine that does this is Mantle, our population model.
It keeps a stored, inspectable roster of every synthetic user.
It samples answers with real variance, because a population answered at temperature zero is one person wearing a thousand hats.
And it calibrates against organic data with one rule: a move is kept only if it improves the questions it targets without hurting the ones it doesn't.
Pew Research showed in September 2026 what happens without that.
A frontier model answering 300 survey questions was off by 12 points on average.
That's the uncalibrated baseline. Calibration is the product.
Finding the sweet spot: the intersection of qual and quant
We think of it as two models working together.
The human model is each synthetic user, built from the core outward, for depth.
The world model is the calibrated population, for breadth.
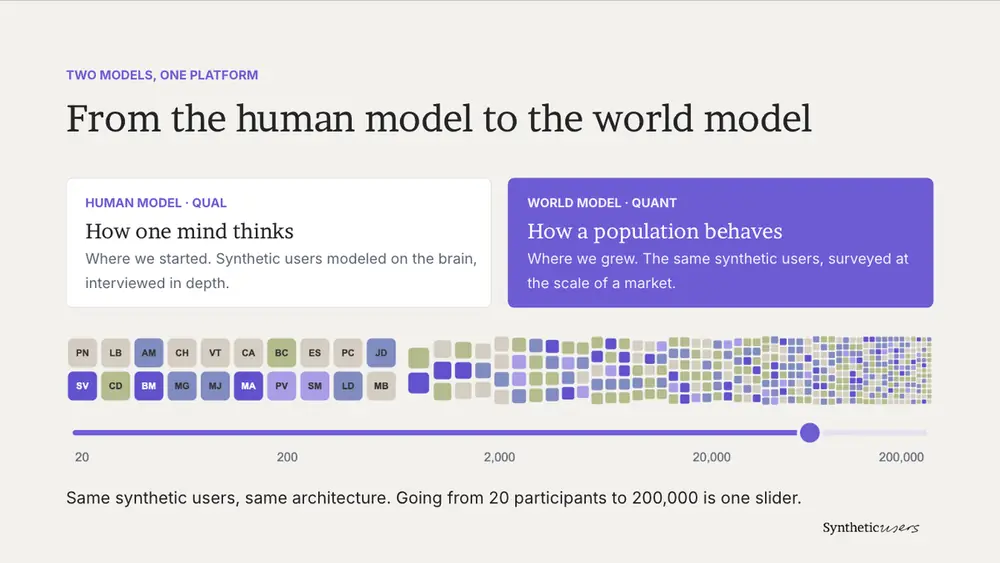
The sweet spot is the loop between them:
Explore a hypothesis in interviews.
Test it across a larger audience.
Go back into the motivations behind the numbers.
Nielsen and Norman called this triangulation: several methods, one understanding.
Synthetic Users lets qualitative depth coalesce with quantitative scale in the same study, even though Nielsen himself is not a fan of Synthetic Users.
Nassim Taleb warned in "The Black Swan" that more data makes you more confident, not necessarily more knowledgeable.
John W. Tukey made the same point from the other side: wanting an answer badly doesn't mean the data holds one.
Qual without quant gives you a story. Quant without qual gives you a number.
Together they give you insight and confidence, and a way to check one against the other.
Proof in public
Most research claims can't be checked. Elections can.
There's a date, a count and a winner.
So we put synthetic users on the record at our Decision Desk.
Brazil, October 2026. Seven of eight polls had Flávio ahead.
Six hundred synthetic users built to match the electorate said Lula by 4.3.
The count: Lula by 3.5.
The US midterms, November 2026. Two hundred synthetic users per state.
We named the winner in 60 of 70 Senate and governor races.
In the six battlegrounds, the poll average missed every one, in the same direction. Our calls landed within about two points.
We also publish the misses. Ten wrong winners. Safe seats too lopsided. Black voters under-read in Mississippi.
One race is a data point. A public scorecard is a track record.
Understanding the mix: getting the best of both worlds
Humans give too much weight to a single vivid story.
Kahneman described it in "Thinking, Fast and Slow."
Cialdini showed it in "Influence: The Psychology of Persuasion," where scarcity makes anything look more valuable.
Pairing the story with the number is the correction.
Synthetic Users also remove three biases that come with human research:
Interaction biases are removed. No participant tells a synthetic interviewer what it wants to hear.
Observer-expectancy effect is neutralized. The researcher's hopes can't leak into the participant's behaviour.
Sampling bias is adjusted. The population is built to the census and the crosstabs, not to whoever answered the recruiter.
What they don't remove is the model's own bias.
LLMs mirror their training data.
Where that mirror is accurate, it's a feature, because it's what parity means.
Where it isn't, we correct it. How we deal with bias covers the full method: diverse data, neutral prompts, an ensemble of models and regular evaluation against organic benchmarks.
A new more efficient world with better products and businesses
With depth and scale in one place, this is what changes:
Richer User Profiles. Every respondent has a core, a memory and a mood, not a row in a spreadsheet.
Predictive Insights. Calibrated populations forecast behaviour, not just describe it. The Decision Desk is the public test of that.
Refined User Journeys. Synthetic users walk the journey and show you where attention lands, down to where their eyes look.
Hybrid Research Methods. Interview, survey, interview again. The same study moves between them in seconds.
Diverse Perspectives. A calibrated population includes the people who rarely answer surveys, including the majority who barely think about your topic.
Bridging Cultural Gaps. Populations are built per country from national surveys, so the same concept can be tested in Lagos and Lyon without a new panel.
Speedier Iteration. Test, learn, change, test again, in the time a recruiter takes to send the first screener.
Deeper Emotional Understanding. Synthetic users have no emotions. But they are built on emotional structure, which is why they surface the drivers behind behaviour.
More than just skincare
Scenario: A skincare company receives thousands of online reviews a month.
Action: Synthetic users are grounded in those reviews.
Result: Words like "confidence," "disappointment" and "relief" keep surfacing. Customers aren't buying skincare. They're buying self-esteem. Products get designed with that in mind.
Airlines dealing with anxiety
Scenario: An airline wants to improve its in-flight experience.
Action: Synthetic users are built from real passenger survey data.
Result: "Anxious" about tight connections shows up again and again. The fix isn't the cabin. It's reassuring notifications about connecting flights.
Evolving Ethical Considerations
As synthetic research deepens, the ethics move with it.
What data grounds a population, who it claims to represent, and how far a simulation is from the people it models all need ongoing guidelines.
A calibrated population is a research instrument. It is not a substitute for being heard.
The sweet spot between qualitative and quantitative is no longer a theory.
It's a loop, with a scorecard.
Explore, test, go back to the why.
Depth and scale, in the same place.